Press the model, keep the oil.
Run real LLMs privately, at 4-bit, on your own GPU.
Pure Rust, no Python at runtime, nothing leaves your machine during inference. Trapetum presses the weights into a small 4-bit code and decodes it straight inside the matmul, so the full weight matrix is never materialized. (The name is the Roman olive press: crush the fruit, keep the essence.)
$ ./trapetum llama-2-7b.cbk          # pure Rust, no Python

loaded  llama-2-7b.cbk  (3.66 GB)  in 3.1 s
prompt:  "The capital of France is"

logits vs HuggingFace (worst)    7.9e-3
top-1 agreement with HF          6 / 6
greedy continuation = HF        16 / 16 tokens   OK
decode throughput               135 tok/s
energy                          2.58 J/token   (2.1x less than fp16)
curl -fsSL get.neuralboot.com | sh
Linux. Windows and details
See the benchmarks · Read the paper
Update, November 2026: a correction to the published 4-bit perplexity (the Llama-2-7B file from the runtime's legacy exporter scores 6.79, not 6.34; the new exporter's file scores 6.10), new CUDA decode kernels at 194.5 tok/s on an RTX 4090 with CUDA graphs, exact speculative decoding at 2.51x on Llama-3.1-8B-Instruct, and Llama-2-70B in 2 bits on one RTX 4090 at 38.4 tok/s (perplexity 4.68 against 6.10 for the new 7B 4-bit file, same 30-window harness), or 4.17 in its PV-tuned 1x16 version at 22.5 tok/s with exact speculative decoding; Llama-3.1-70B-Instruct, a conversational 70B, reaches 21.3 tok/s on chat prompts with exact speculative decoding from a 2-bit Llama-3.1-8B-Instruct drafter. Code on the repository's main branch, not yet in the app. Read the update.
Real Llama-2-7B, 4-bit, in pure Rust. No Python at runtime.
Watch a recorded race of DeepSeek-R1-Distill-Qwen-7B, 4-bit vs fp16, on two identical RTX 4090s, or read the plain-language overview.
What do these numbers mean?
- 16/16 tokens match HuggingFace: given the same prompt, the 4-bit model emits the exact same next 16 tokens (greedy) as the Hugging Face forward pass of the same quantized weights. Proof the quantization, the kernel and the Rust pipeline are correct, not approximate (worst-case logit gap 7.9e-3).
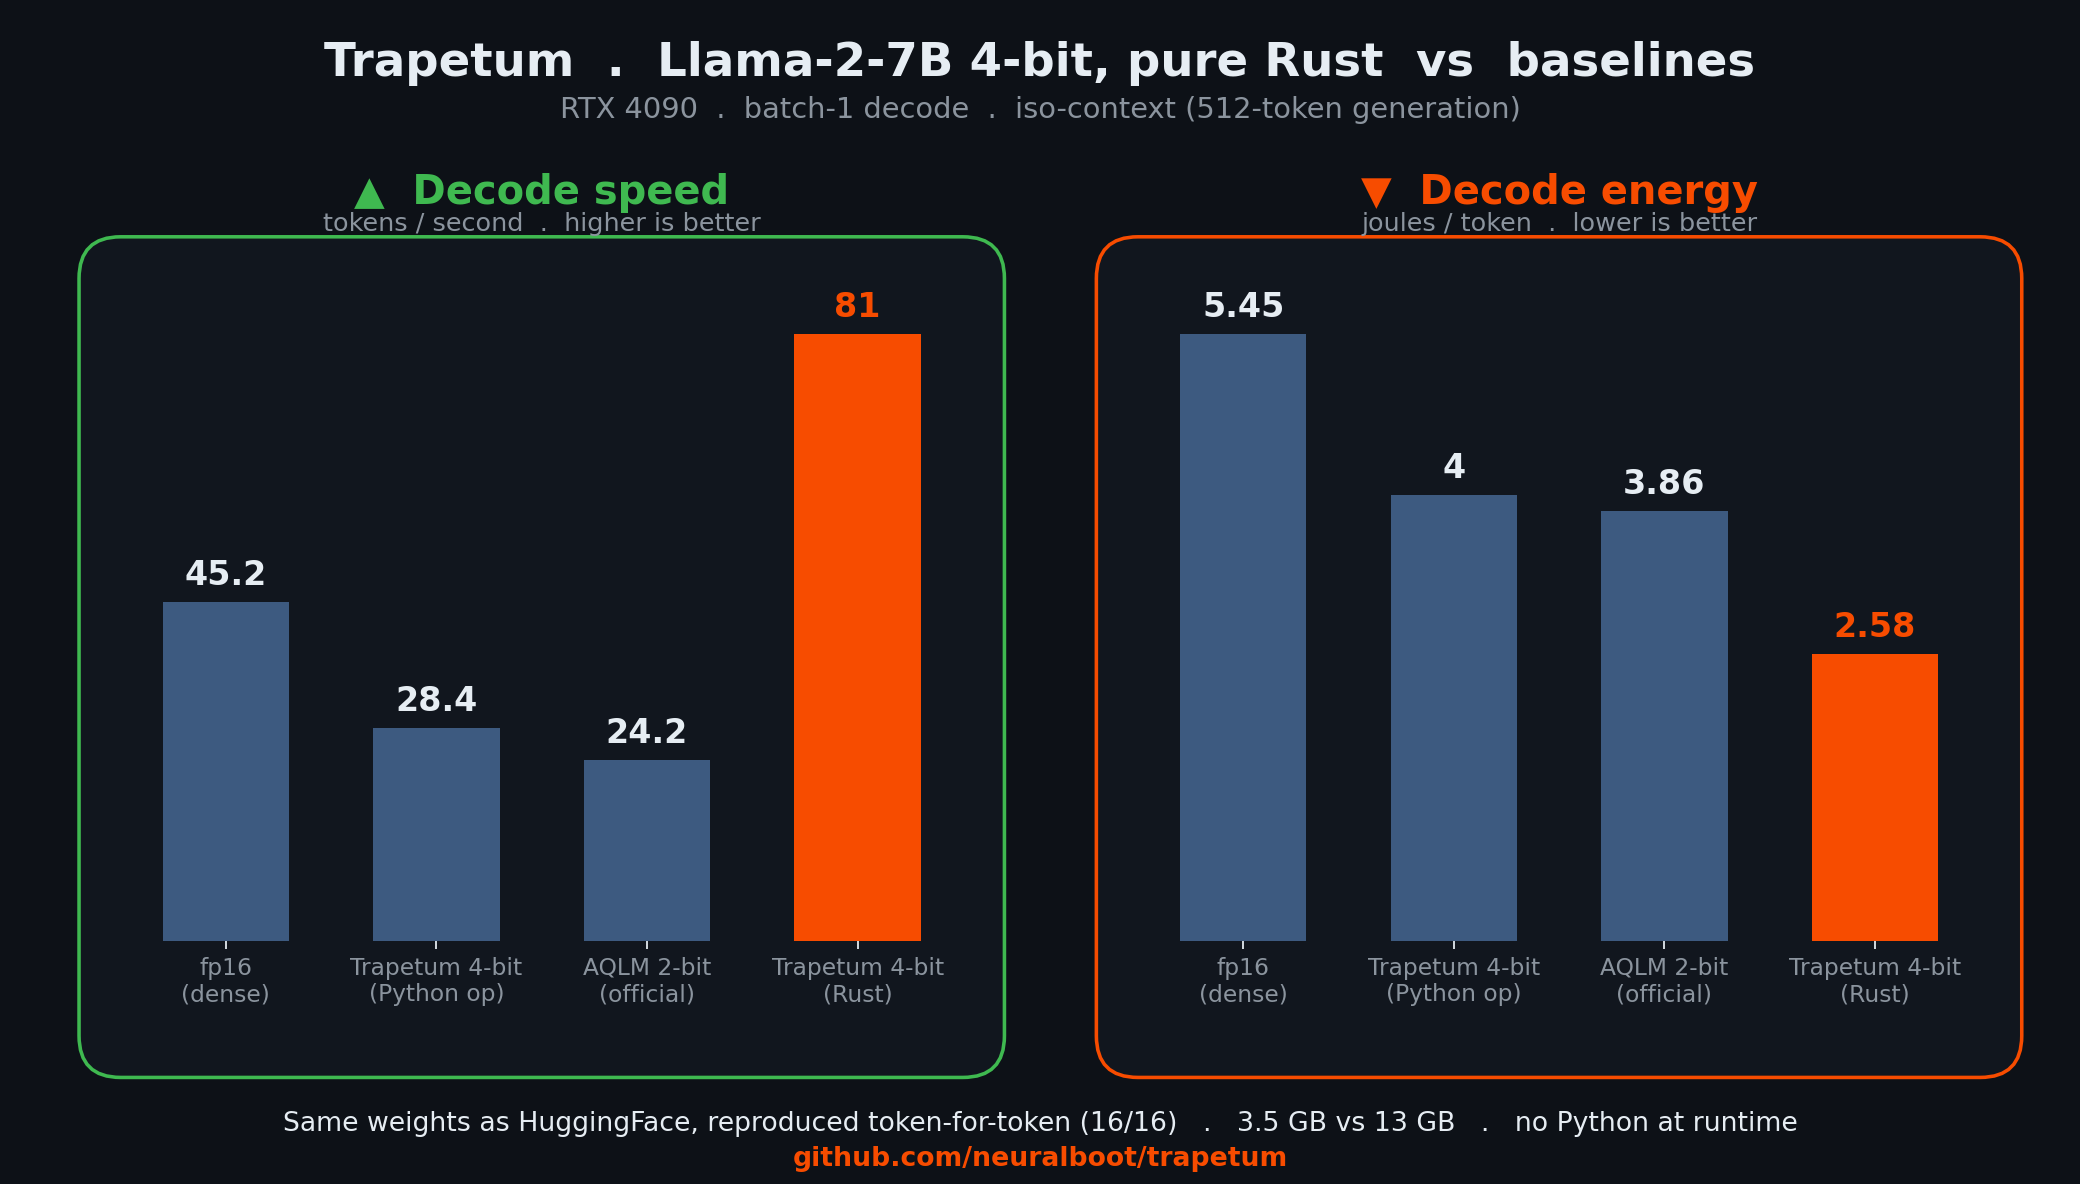
- 135 tok/s on one RTX 4090: generation speed, one token at a time (batch 1), on a single consumer GPU. How fast it “types” the answer. Measured with the previous runtime; the November 2026 decode kernels, not yet in an app release, reach 194.5 tok/s on the same GPU with CUDA graphs, over a 512-token generation.
- 3.66 GB on disk (4.7 GB VRAM), vs 13.48 GB fp16: the weights shrink 3.7×, from 13.48 GB (16-bit) to 3.66 GB (4-bit; 3.75 GB from the new exporter), so a 7B model fits on a small or consumer GPU instead of needing a datacenter card.
- 2.1× less energy per token: each generated token costs 2.1× less energy than fp16 (2.58 vs 5.45 joules per token, measured from GPU power draw). Cheaper and greener to run.
NVIDIA CUDA + APPLE METAL
Runs on any modern NVIDIA GPU, and on Apple Silicon
The RTX 4090 above is only our reference card. Trapetum has two GPU backends: CUDA for any Ampere, Ada or Hopper NVIDIA card (benchmarked on RTX 4090, A40 and H100), and Metal for Apple Silicon Macs, M1 to M4 (benchmarked on M4). The 4-bit memory win is universal (a 7B in 3.66 GB fits an 8 GB card); the decode speedup follows the bandwidth law, largest where memory bandwidth is scarcest. See the per-GPU table and the Apple M4 numbers.
APPLE SILICON SUPPORTED · AMD NOT YET
Now on Apple Silicon; AMD is not supported yet
The fused 4-bit decode is ported to Metal and runs on the Apple GPU today (M1 to M4), no NVIDIA needed. Download for macOS or see the measured M4 numbers. There is no AMD backend (ROCm / HIP) yet: the pure-Rust runtime and the codebook format are already portable, so the work would be the kernels. The 4-bit memory win would carry over unchanged, and the decode speedup would follow the same bandwidth law. Want AMD first? Tell us your GPU.
It reproduces HuggingFace, token for token
Loaded from a 3.66 GB .cbk file, the runtime decodes the same quantized weights as
HuggingFace and reproduces its greedy generation exactly, with no Python in the loop. The terminal
output above is a real run, not a mockup: worst-case logit gap 7.9e-3, greedy continuation identical
for 16 of 16 tokens. Full model-level results.
Speed and energy, one machine (previous runtime)
Decode speed and energy for the same Llama-2-7B on an RTX 4090, batch-1 decode, iso-context (512-token generation). The pure-Rust runtime is the fastest and the lowest-energy path; memory and accuracy are on the benchmarks page.
Honest limits
- It does not beat dense fp16 on accuracy. Nothing does; quantization trades a little perplexity for a lot of memory.
- The kernel speedup is a memory-bandwidth law: largest where memory bandwidth is scarcest, near parity on an H100 where fp16 is already near roofline.
- Batch-1 decode for now. Batched throughput is an open problem, marked as such.
The code is public, everything is measured on real hardware and reproducible with one command, including the negative results, and the November 2026 results are summarized on the benchmarks page.